Maintenance log and work order agents for mining
The short version: the work order written at end of shift from memory is the reason your maintenance history can’t be trusted. A maintenance log agent takes a technician’s voice at the asset, writes a correctly-coded work order into the CMMS, attaches the right equipment — and chases the meter reading before the technician leaves the bay.
Last updated:
The problem, precisely
Maintenance data quality dies at the point of capture. A fitter finishes a job at 2pm and writes it up at 5:40pm, from memory, in a hurry, against whichever asset number was easiest to find. Fault codes are guessed. Parts consumed are approximated. Meter readings are skipped. The reliability engineer downstream is doing failure analysis on fiction.
McKinsey’s research on analytics-driven maintenance finds predictive maintenance typically reduces machine downtime by 30 to 50 percent (McKinsey & Company, 2017) — but every one of those programmes stands on capture quality. Bad work-order data doesn’t just waste the technician’s evening; it quietly caps what your entire reliability programme can ever achieve.
What the agent does
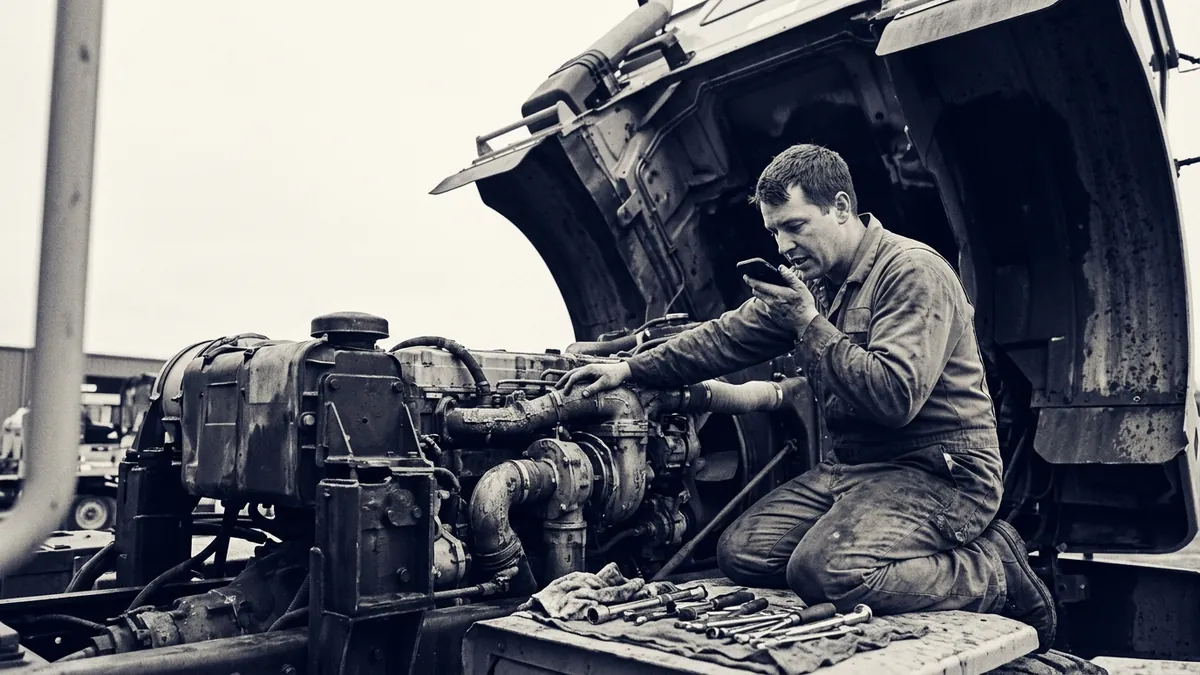
Capture at the asset. The technician talks while the job is fresh — what was found, what was done, what was consumed, what still needs attention. Voice or text, offline-tolerant, gloves-compatible.
Code correctly. The agent writes a structured work order into your CMMS: right asset from the register, right failure code from your taxonomy, parts against inventory, labour hours captured rather than reconstructed.
Chase what’s missing. Meter reading not mentioned? Fault code ambiguous? The agent asks before the technician leaves the asset — the only moment the answer is cheap.
Deduplicate and connect. New defects are checked against open work orders on the same asset, and follow-up work raises notifications rather than getting lost in a verbal “someone should look at that.”
Maintenance capture today vs with an agent
| Today | With an agent | |
|---|---|---|
| When it’s written | End of shift, from memory | At the asset, in the moment |
| Asset attribution | Whichever number was handy | Validated against the register |
| Failure coding | Guessed | Taxonomy-checked |
| Meter readings | Often skipped | Chased at capture |
| Duplicate work orders | Common | Checked before creation |
| Reliability data quality | Fiction-adjacent | Trustworthy at source |
Built for the conditions
Offline capture that queues and reconciles. Voice as the primary interface, tested with your crews’ accents, PPE and workshop noise during shadow mode. And a hard scope boundary: the agent reads from historians and condition systems where useful, and never writes to control systems — coordination layer only.
What it connects to
CMMS/EAM: SAP PM, IBM Maximo, Pronto, Mex, Fiix, Limble.
Inventory: parts consumption against your stores system.
Condition monitoring: read-only context from historians and OEM platforms, so a voice-reported symptom can be matched to a trend. The upstream pattern — condition signal to work order without a human reading a dashboard — is covered at predictive maintenance.
Frequently asked questions
Will fitters actually talk to it?
When it saves them the 5:40pm write-up, yes. The design target is that capture at the asset is faster than the paperwork it replaces — and shadow mode measures exactly that before anything goes live.
Our failure-code taxonomy is a mess. Does that break this?
No — it’s usually the first thing the deployment improves. The agent applies the taxonomy consistently, which surfaces where the taxonomy itself is ambiguous. Several clients treat the first month’s output as a taxonomy review.
Can it raise work from a voice note about “something looking off”?
Yes — as a notification for planner review, coded as an observation, never as a self-approved work order. Planners decide what enters the schedule.
Does it touch our control systems?
No. Read-only from historians where useful; writes go to the CMMS only. Safety-rated systems are out of scope by design.
How long to deploy?
Typically 4–6 weeks on a supported CMMS, including two weeks of shadow mode alongside your existing process.